Claude Fable 5 Model Release
Anthropic's Claude Fable 5 was released this week. We tested it on both APEX-Agents and APEX-SWE ahead of the launch. Here's how it performed.
APEX-SWE Benchmark
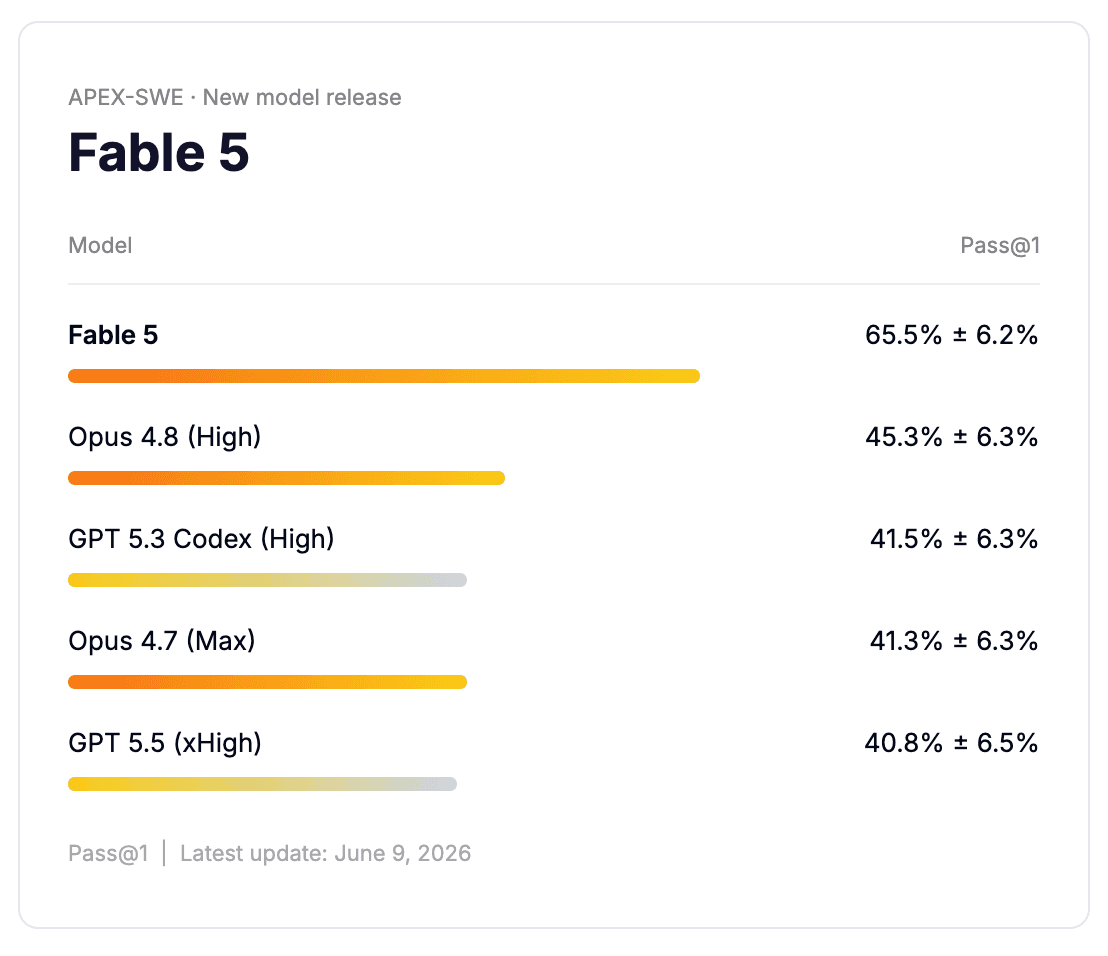
New APEX-SWE leader
Benchmark update
Fable 5 takes the #1 spot at 65.5% Pass@1, 20 points ahead of Opus 4.8 (45.3%).
It is the largest single jump we have recorded between consecutive frontier releases on APEX-SWE.
Integration vs. Observability
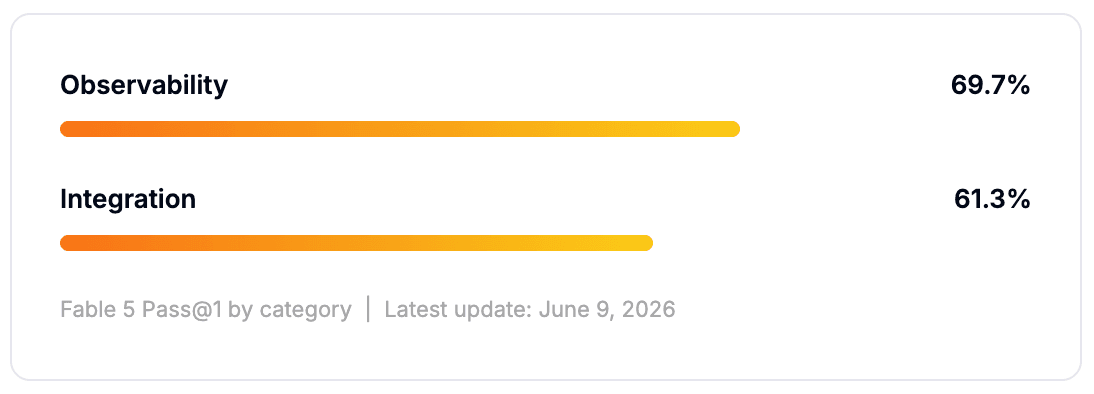
APEX-SWE tests two categories: Integration (building and connecting systems) and Observability (diagnosing and debugging).
Fable 5 leads both. Integration comes in at 61.3%. The standout is Observability at 69.7%, 26 points ahead of Opus 4.8.
Observability has been the bottleneck for every model we have measured. Fable 5 is the first to clear 50% on the category, and the only model that scores higher on Observability than on Integration. Every other model shows the reverse.
How it works
What changed is how Fable 5 works. Where Opus 4.8 reads code one file at a time, Fable 5 investigates in parallel: 10.4 parallel tool calls per trajectory versus zero for Opus 4.8. It searches code, reads files, runs tests, and queries logs at once, instead of chasing one hypothesis at a time. It also reads surgically. Full-file reads dropped 91%, from 9.9 calls per trajectory to 0.8, as it shifted to targeted commands that pull only the lines it needs. The pattern is higher leverage, not more effort.
Fable 5 spends less of its budget searching and more validating, testing as it goes and catching issues during edits rather than after. It rewrites less too: 3.8 edit iterations versus 6.0 for Opus 4.8. The result is 10% fewer total tool calls and 36% less reasoning text than Opus 4.8, with a 26 point Observability gain.
APEX-Agents Benchmark
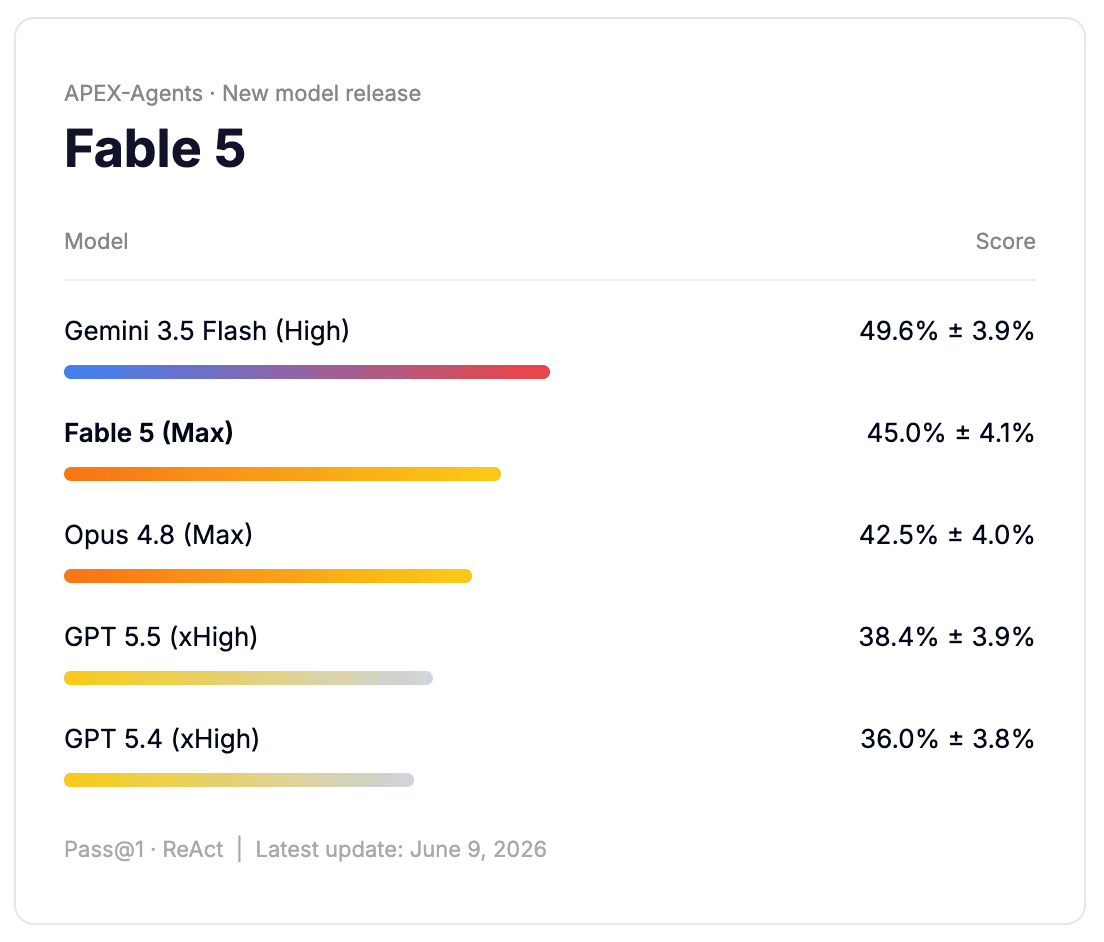
2nd on APEX-Agents
Benchmark update
Fable 5 (Max) scores 45.0% Pass@1, behind Gemini 3.5 Flash (49.6%) and ahead of Opus 4.8 (42.5%).
Efficiency
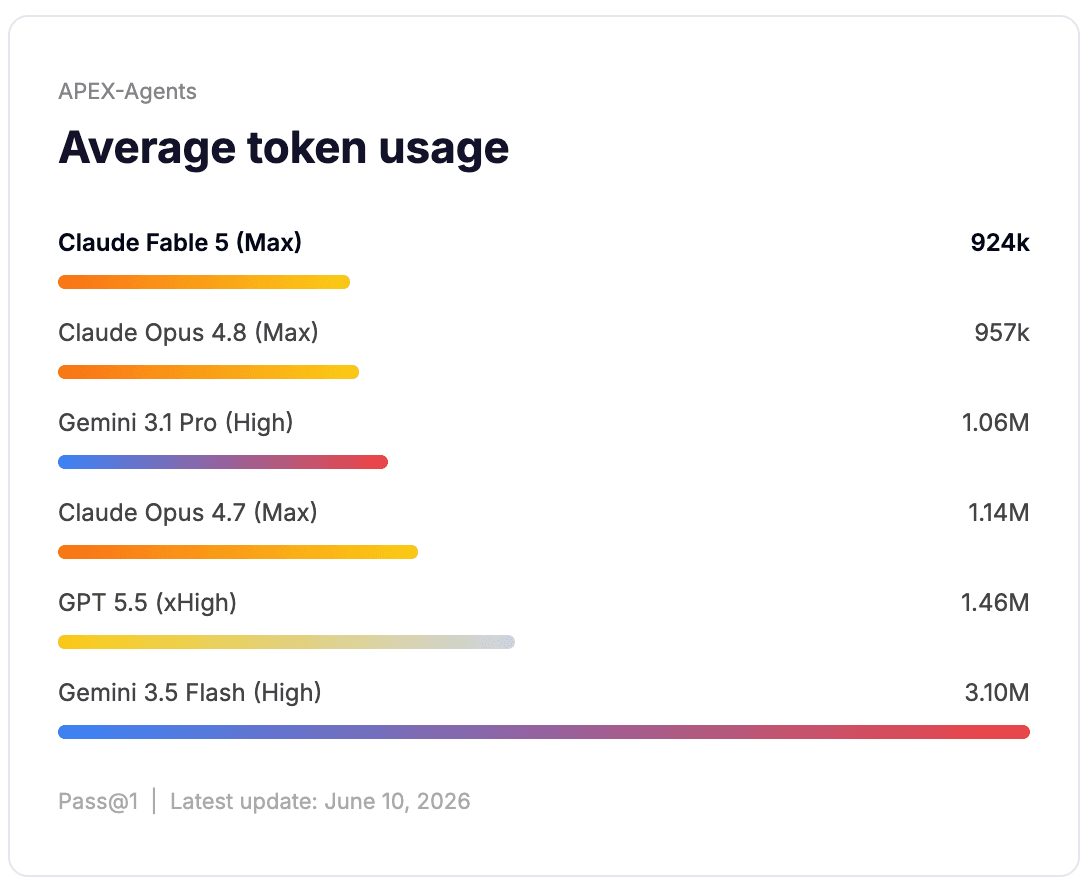
Fable 5 reached 2nd overall while spending far fewer tokens: 70% less than Gemini 3.5 Flash and 37% fewer than GPT 5.5. It also ran in fewer steps, 22.6 on average versus 59.4 for Gemini.
Domain breakdown
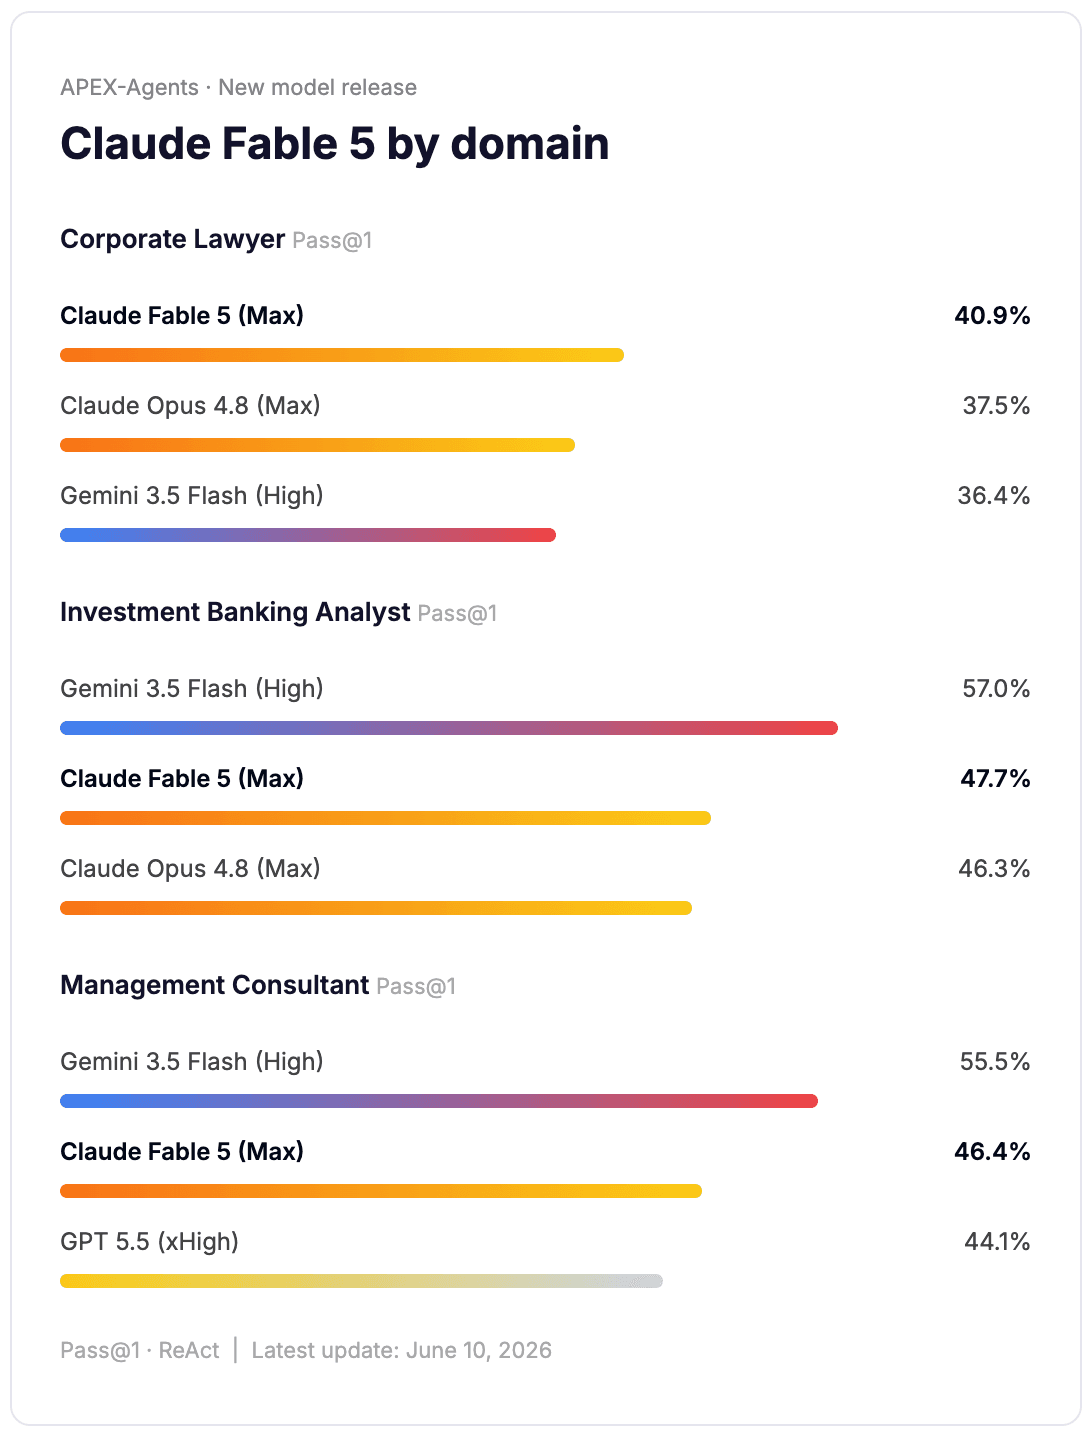
Fable 5 leads in Law and places 2nd in the other two domains, Pass@1:
- Corporate Law: 40.9% (1st)
- Investment Banking: 47.7% (2nd)
- Management Consulting: 46.4% (2nd)
Across 4 runs, Fable solved 246 of 480 tasks, including 8 that no other model has solved. All 8 are in Law, spanning Family Law, Consumer Protection, Corporate Tax, and Securities. They cover litigation, advisory, and public-company compliance.
APEX is our set of benchmarks that reflect a broader shift in how the workforce is evolving by measuring whether AI can complete professional, economically valuable work.